Archives & GenAI | Program

September 30, 2026

Generative AI is changing how archives create, manage, preserve, and provide access to collections. It is also raising new questions about authenticity, copyright, licensing, provenance, and what it means to steward the historical record in an environment where authentic and synthetic records increasingly coexist.

Building on the work of the Trust in Archives Initiative, this one-day virtual symposium brings together a cross-section of perspectives to explore how generative AI is affecting archives and the broader communities that work with archival materials. Speakers will share current initiatives, practical experiences, and emerging approaches to authenticity, copyright and licensing, responsible access and use, and maintaining trust in archival collections.

The symposium is designed to encourage conversation across disciplines. Throughout the day, participants will hear how different organizations are approaching common challenges, explore where priorities and practices align, and consider where further collaboration is needed. The day will conclude with an open discussion, providing an opportunity to exchange ideas, identify shared needs, and help inform the next phase of community efforts.

SESSION ONE

8:00 am
Welcome and Introductions

8:10 am
Stewardship and GenAI: A Keynote Conversation

8:45 am
Cybersecurity, AI, and Us. A New DPC Technology Watch Guidance
Note Series on Cyber Security for Digital Preservation

9:05 am
Research. Findings from research efforts on how GenAI is already changing archival practices, what changes archivists are expecting, and how institutions are responding.

How Archivists Respond to the Threat of Fake History

AV Archivists’ Perceptions of AI: Findings from the AMIA Salary and Demographics Survey of the Field


SESSION TWO

9:45 am
Mapping the Response. As GenAI evolves, so does the response. Presenters will share how their initiatives are addressing emerging challenges, helping practitioners understand what’s at stake, and developing new standards, policies, and approaches for the work ahead.

Protecting Trust in the News Industry with Content Credentials and Publisher Identity

Updates on the SAA AI Task Force

FADGI’s New Resources on Content Authenticity and Provenance for AI-impacted AV Collections Content

Metadata Transparency – Moving from Proof of Concepts to Real World Adaption and Integration

InterPARES: Responsible Use of AI

An Overview of Content Provenance Technology via C2PA and CAWG


10:50 am
Reports from the Field. No single organization or discipline has the full picture of how genAI is impacting our field. The goal isn’t to present finished solutions, but to hear where organizations are at this moment and see where experiences overlap or diverge.

Defending Audiovisual Human Rights Documentation

Why Ask WAAI: Web Archiving and AI

  • Jefferson Bailey, Internet Archive

Reframing the Colonial Gaze: AI, Archives, and Artistic Practice

Roping in AI: How TAMI Adapts Policy & Workflow for New Tech

AI and Archives: Navigating New Access Demands

GenAI and Digital Evidence in the Forensic Community


11:20 am
Open Forum


SESSION THREE

12:00 pm
Licensing. Perspectives from across the archival footage licensing landscape on how generative AI is reshaping licensing, including emerging attribution and consent frameworks and shifting client expectations.

“I Killed a Business Model”

Global ImageWorks | AI vs. AI: Licensing in the Age of Artificial Intelligence

AI and Licensing: Are the Rules of the Game Changing?

Periscope Films

Building the Next Generation of Sharing: CC Licenses and CC Signals

12:50 pm
Copyright & AI: An Overview

1:15 pm
The Future of Knowledges: Archives After AI

1:35 pm
Open Forum

2:00 pm
Closing Comments

SPEAKERS
Ottar A.B. Anderson oversees the research and development, metadata strategy and quality control within SEDAK, the GLAM (Galleries, Libraries Archives and Museums) imaging service of Møre og Romsdal County in Norway, hosted by the Intermunicipal archive of Møre og Romsdal. He is one of the founding members of the Digital Object Authenticity Working Group (DOAWG) and expert member of the joint working group 26 in the ISO committee 42 – “Imaging system capability qualification for archival recording and approval”. Please check out www.doawg.org for more info about community collaboration on metadata and authenticity.
Rachel Antell has worked in documentary film production for 25 years, and over a decade of those as an archival producer. In 2014 she co-founded Sub-Basement Archival where she’s had the honor of working on dozens of documentaries that have screened worldwide, and garnered FOCAL Awards and an Emmy nomination for research and use of archival footage. In 2023, Rachel co-founded the Archival Producers Alliance (APA) to organize archival producers, educate the film community about the craft, and advocate for the field. There she helped lead the APA to publish the first industry guidelines and tool kit for the responsible use of generative AI in documentary; as well as co-founding the Trust in Archives Initiative which builds tools to safeguard audiovisual library and archive collections in the synthetic age.
Patricia Aufderheide is University Professor, School of Communication, American University, the author of, among many others, Kartemquin Films: Documentaries on the Frontlines of Democracy and (with Peter Jaszi)Reclaiming Fair Use: How to Get Balance Back in Copyright, and honoree of many awards, including Emmy recognition for life achievement in improving the television industry in 2026, by induction into its Silver Circle.


Jefferson Bailey is Director of Archiving & Data Services at Internet Archive. Prior to Internet Archive, he worked on strategic initiatives, digital collections, and digital preservation at institutions such as Metropolitan New York Library Council, Library of Congress, Brooklyn Public Library, and has worked in the archives at NARA, NASA, and Atlantic Records. He has an MLIS in Archives from University of Pittsburgh.
 

Lou Burkart is working as archival curator at the Eye Filmmuseum in Amsterdam, focusing on documentaries, female directors and queer film culture. They are also Secretary General of CCAAA, the Co-ordinating Council of Audiovisual Archival Associations. Previously they worked as restoration supervisor at the DFF – Deutsches Filminstitut in Frankfurt am Main. Their restorations premiered in festivals such as Il Cinema Ritrovato, Giornate del Cinema Muto, Festival Lumière and Cannes Classics. They presented their audiovisual projects and research at international conferences.
Dr. Luciana Duranti is Professor Emerita of archival science and diplomatics in the School of Information of the University of British Columbia (UBC), in Vancouver, Canada, and Affiliate Professor at the University of Washington at Seattle, United States. She is the Principal Investigator of the InterPARES research project, which, since 1998, has developed theory and methods for the creation, maintenance and preservation of trustworthy digital records across technologies. She has been the President of the Society of American Archivists and the Association of Canadian Archivists. Since 2015, she is the Chair of the Canadian Government Standards Board committee for Electronic Records as Documentary Evidence.” Feel free to cut it to your preferred length.
Williams Rossa Cole is a documentary film professional with 25 years experience as a producer, director, editor and archival producer with films premiering at Sundance, Rotterdam, on HBO, RTE, Amazon and other outlets and festivals. He earned a MSc (distinction) from the LSE as a Fulbright Scholar and graduated from Columbia University. He completed a Certificate in AI Strategy at eCornell, a CompTia Security + Certificate and is currently engaged in the Information Warfare Certificate at University of Arizona. In 2024 he published “Beyond Deepfakes: Synthetic Moving Imagery and the Future of History” in The Journal of Information Warfare.

Charlie Eckert is an archival producer and researcher who uses investigative journalism skills to locate hard-to-find materials and elevate narrative storytelling. He works at Global ImageWorks, an independently owned archive built by researchers for researchers, and is part of the company’s internationally recognized research and clearance team. He is a member of the Trust in Archives Initiative Content Licensing Working Group and helped craft the initiative’s licensing templates. Charlie holds a Master of Science from Columbia Journalism School.
Brenda Gunn is the Associate University Librarian for Special Collections and Preservation at the University of Virginia Library. She has co-written a monograph on United States archival revolutions since 1980 to be published this fall by the Council on Library and Information Resources and is co-editing a special section of the American Archivist journal on artificial intelligence in archival enterprise. A certified archivist and a Distinguished Fellow of the Society of American Archivists (SAA), Brenda currently serves as SAA’s 81st President.
Dave Hansen is the Executive Director of Authors Alliance. Prior to joining the Authors Alliance, Dave was an Associate University Librarian and Lead for Copyright & Information Policy at Duke University Libraries, where he was responsible for core research and collections support for faculty and students. Dave has testified before Congress, the U.S. Copyright Office, and the USPTO on copyright, AI, open access, and fair use issues affecting academic authors and universities, and has experience teaching and advising researchers, publishers, and librarians on copyright, fair use, and authors rights. He received his JD and MSLS from UNC Chapel Hill.
Elizabeth Hansen is the Executive Director of the Texas Archive of the Moving Image (TAMI), a non-profit organization dedicated to discovering, preserving, and providing access to Texas’s moving image heritage. She oversees TAMI’s strategic operations, archival preservation workflows, community partnerships, and licensing initiatives.
 

Shanna Hollich. As Senior Manager, Learning and Training, Shanna supports all of CC’s programs and projects by identifying and developing professional development and learning opportunities that are relevant to CC’s mission, including (but not limited to) the CC Certificates. Prior to joining CC, Shanna worked for 15 years as a librarian across multiple institutions – K-12 school, public, government, and academic. They have worked in public/access services, technical services and cataloging/metadata, and administration, ultimately serving as director for the John Stewart Memorial Library at Wilson College and the Guthrie Memorial Library in Hanover, PA. Their research during this time primarily involved copyright reform, cultural heritage, open access, open education, and social justice.
Krista M. Hollis is the Associate Archivist at The Menil Collection and a member of the Trust in Archives Initiative Steering Committee. She is active in local and regional cultural heritage groups with research interests including sustainability, systems thinking, and reparative practices; these are the lenses through which Krista approaches the challenges presented by emerging technologies.
 

Jesse Johnston is a Clinical Assistant Professor at the University of Michigan School of Information. Johnston has been active in the cultural heritage field as an administrator, librarian, archivist, and civil servant. He teaches courses on digital preservation, information organization, and digital preservation and is currently researching the impacts of generative AI on archival reference practices.
 

Heather Lowrie. A senior cybersecurity, technology and resilience leader, Heather Lowrie has worked in complex, highly regulated environments, supporting large-scale transformation and regulatory compliance initiatives and advising senior stakeholders on technology, security and resilience. Heather holds a first-class honours undergraduate degree in Law from the University of Dundee, a Postgraduate Diploma in Information Technology, and two master’s degrees from the University of Edinburgh, including one by research, all awarded with distinction. Her executive and non-executive experience includes serving as the first Chief Information Security Officer at The University of Manchester and leading security, risk and resilience for Scotland’s first digital-first Census. She has served as a member-elected Trustee of the UK Cyber Security Council and as Co-Chair of the ISC2 UK Advisory Council. She is a Fellow of both the British Computer Society and the Chartered Institute of Information Security, and a guest lecturer at The University of Manchester.
Bertram Lyons is a Director in Product Management at Magnet Forensics, overseeing evidence trust and data services. Prior to joining Magnet Forensics, Bert was the CEO at Medex Forensics (acquired by Magnet Forensics). Bert has over 20 years of experience leading consultants and development teams to manage large collections of digital assets and data, and to create innovative, flexible, and user-center software for clients where digital assets are a core function of their organization. His background specializations include the acquisition, management, analysis, and preservation of evidential, documentary, research, corporate, and archival data.
Before founding Medex Forensics, Bert served as Managing Director for Software at AVP, an information innovation company, and prior to that worked as a digital archivist for the American Folklife Center (AFC) at the Library of Congress. Bert has supported migration and software development projects for organizations nationwide, including the Federal Bureau of Investigation (FBI), the Smithsonian Institution, the Library of Congress, the JFK Presidential Library Foundation, HBO, Paramount Pictures, University of Kentucky, Indiana University, Yale University, Harvard University, Facebook, and the Mayo Clinic, among many others. Bert is an Associate Member of the American Academy of Forensic Sciences (AAFS) and an active member of the Scientific Working Group on Digital Evidence (SWGDE). He has received certification from the Academy of Certified Archivists and is a graduate of the Archives Leadership Institute. He holds an MA in museum studies with a focus in American studies and archival theory from the University of Kansas.
Kate Murray is the Digital Projects Coordinator in the Digital Collections Management and Services at the Library of Congress where she leads the Federal Agencies Digital Guidelines Initiative (FADGI) Audio-Visual Working Group and the Sustainability of Digital Formats website. Prior to joining the Library of Congress, Kate was the Digitization Process Development Specialist at the National Archives and Records Administration specializing in standardizing and documenting moving image and audio formats. Previous affiliations include the University of Maryland Libraries, Emory University Libraries, University of Cape Town Libraries and NYU Libraries. Kate is a member of AMIA (Preservation Committee co-chair 2010-2013), IASA (Technical Committee member), SMPTE, ISO/TC171/SC2 (PDF standards committees) and ISO/IEC JTC 1/SC 34/JWG 7 (EPUB standards committee). She was the co-chair of the Mellon Foundation/Digital Preservation Coalition’s Task Force on Technical Approaches to Email Archiving, co-coordinator of the 2015 Archiving Email Symposium, co-coordinator of the 2017 Architecture, Design and Engineering Asset Summit Symposium and co-coordinator of Born to Be 3D in 2018. In 2019, she received one of the inaugural JTS Awards for contributions to the technology of the audiovisual archiving field. Kate received her undergraduate degree in Medieval Literature from Columbia University and her MBIBL from the University of Cape Town.
Dale Nelson is a partner in the West Adams boutique Donaldson Callif Perez.  Prior to joining the firm, Dale served as Vice President and Senior Intellectual Property counsel at Warner Bros. for over 25 years.  Dale specializes in issues related to copyrights, trademarks, personal rights and clearance, championing the free speech rights of clients in the filmmaking and creative industries.  Dale is also a frequent speaker on IP topics and is currently Immediate Past Chair of AIPPI-US, the US chapter of AIPPI, an international IP organization with over 80 countries represented.  Dale is also on the Endowment Board of the Western Center on Law and Poverty, and on the Board of the Independent Shakespeare Company, a non-profit entity hosting free Shakespeare productions in Los Angeles’ Griffith Park.  Dale was recently recognized in Variety’s 2024 Legal Impact Report for her work with independent filmmakers.
Yvonne Ng is an audiovisual archivist and a Senior Program Manager at WITNESS, where she trains and supports people to archive and preserve their human rights documentation. She currently serves on the Board of the CAW Collective and on the steering committee of the Trust in Archives Initiative (TAI). In 2024, Yvonne received the Alan Stark Award from the AMIA in recognition of her contributions to moving image archives and the association. Yvonne holds an M.A in Moving Image Archiving and Preservation from New York University.
Kay Page is the Managing Director of FOCAL International, the not‑for‑profit trade association representing the global footage and content licensing industry, alongside technical specialists in post‑production, preservation, restoration and related technologies. With a career rooted in television – including roles at ITV and All3Media – and experience as an independent consultant, Kay has extensive expertise in archiving strategy, rights management and licensing. She is a passionate advocate for the creative and commercial value of archive content.
Brendan Quinn is a media technology expert and the Managing Director of the International Press Telecommunications Council (IPTC). With over two decades of experience in media innovation, he has led major projects including the development of the Associated Press’s APVideoHub.com syndication platform, the re-architecture of the BBC’s digital infrastructure, and the implementation of advanced content management systems at the BBC and at Fairfax Media in Australia. His work at IPTC reflects a deep commitment to advancing the global standards and technology frameworks that power the modern media industry, with a particular focus on trust and authenticity.
Brian Real is an assistant professor in the School of Information Science at the University of Kentucky. Real holds a PhD in information studies and a master of library science from the University of Maryland. Real is an active researcher on public libraries and film archives, and his recent efforts in the latter area have involved working with the Association of Moving Image Archives to document workplace conditions in the field. His work has been published in The Moving Image, Journal of Archival Organization, Library Quarterly, Public Library Quarterly, Historical Journal of Film, Radio, and Television, and other scholarly outlets.
Megan Scott is Digital Archivist at Fondren Library, Rice University, where she leads digital preservation efforts for the Woodson Research Center Special Collections & Archives. Prior to joining Rice, she served as Digital Curation Librarian at Texas Tech University Libraries. She has published on the topics of institutional repositories and digital libraries, digital project management, and, more recently, AI and cultural heritage collections. She holds a B.B.A. in Marketing from Texas Tech University, and an M.L.S with a certificate in Digital Content Management from the University of North Texas.
Eric Scouten is a principal scientist and identity architect for the Content Authenticity Initiative at Adobe. He leads the team developing open-source SDKs for content provenance and co-chairs the Creator Assertions Working Group, which defines technical standards for using digital credentials to provide attribution in digital content. In his spare time, he enjoys exploring the world (60+ countries so far) and blogging about his adventures.
 

Nick Spark is the co-founder and curator of Periscope Film, a leading historic film archive based in Los Angeles and vice president of the non-profit Humanus Documentary Film Foundation. Nick has an MFA in film production from the USC School of Cinematic Arts. He is also an Emmy award winning documentary filmmaker whose projects have appeared on PBS, History Channel and National Geographic. He has also spent time in front of the camera and the microphone, appearing on PBS’ “NOVA” and “History Detectives”, the “Decoder Ring” podcast and National Public Radio’s “All Things Considered”. He recently worked with the University of Maryland, University of Southern California and Underwriters Laboratory to restore a previously lost 28mm industrial film from 1917, entitled “An Unbeliever Convinced.”
Garth Stewart is Head of Good Practice at the Digital Preservation Coalition (DPC). Garth works with the Good Practice team to understand what good practice in digital preservation looks like and where it is being carried out, towards facilitating ways and means to share that knowledge for the benefit of DPC’s Members and beyond. Garth came to DPC in 2025, having led the Digital Records Unit at National Records of Scotland.
 

Dr. Keir Winesmith is the Chief Digital Officer at the National Film & Sound Archive (NFSA), mentor in the Creative Australia’s CEO Digital Mentoring Program, and co-founder of the bi-monthly Cultural Data Salon for Sydney cultural workers. His book, co-authored with Dr. Suse Anderson, is ‘The Digital Future of Museums’ (Routledge, 2020). Keir has a background in art, strategy and consulting, and has collaborated on award-winning projects that blend digital and culture across the globe. In 2018, he was named in Fast Company’s 100 Most Creative People in Business for this work. Keir holds hold a Ph.D. in new media and writes and speaks frequently on the intersection of digital and the arts, in particular, the role of digital as an agent for organisational change.

 

Archives & GenAI Symposium


September 30, 2026
8:00am – 2:00pm (Pacific)

Generative AI is changing how archives create, manage, preserve, and provide access to collections. It is also raising new questions about authenticity, copyright, licensing, provenance, and what it means to steward the historical record in an environment where authentic and synthetic records increasingly coexist.

Building on the work of the Trust in Archives Initiative, this one-day virtual symposium brings together a cross-section of perspectives to explore how generative AI is affecting archives and the broader communities that work with archival materials. Speakers will share current initiatives, practical experiences, and emerging approaches to authenticity, copyright and licensing, responsible access and use, and maintaining trust in archival collections.

The symposium is designed to encourage conversation across disciplines. Throughout the day, participants will hear how different organizations are approaching common challenges, explore where priorities and practices align, and consider where further collaboration is needed. The day will conclude with an open discussion, providing an opportunity to exchange ideas, identify shared needs, and help inform the next phase of community efforts.


Symposium Keynote:  Stewardship and GenAI: A Keynote Conversation

As generative AI is rapidly changing how audiovisual materials are accessed, reused, and understood, archives are facing new questions about openness, stewardship, and trust. In this keynote conversation, Brenda Gunn, Associate University Librarian for Special Collections and Preservation at the University of Virginia and president of Society of American Archivists, joins Dave Hansen, Executive Director of Authors Alliance, to talk about how long-standing values around open access, responsible use, attribution, and donor intent can help inform the decisions archives make around the potential impact of the tech on their collections.

While both speakers share a commitment to openness and access they bring different perspectives to how those principles apply as genAI continues to evolve. The conversation will look at some of the practical questions archives are already navigating: How do we maintain access while considering commercial use of collections? Will donors be less willing to make materials publicly available without greater protections? And what does meaningful attribution look like when archival materials are being used in new ways?


THE PROGRAM

Sessions throughout the day will look at the work already underway, from security and authentication to licensing and copyright, while mapping how organizations and initiatives are responding across the broader community.

  • Research
    Findings from two research efforts on how GenAI is impacting archival practices.
  • Security
    The security concerns for collections and institutions as the technology evolves.
  • Mapping the Response
    As GenAI evolves, so does the response. Presenters will share how their initiatives are addressing emerging challenges, helping practitioners understand what’s at stake, and developing new standards, policies, and approaches for the work ahead.
  • Reports from the Field
    No single organization or discipline has the full picture. This session will offer snapshots from individual organizations on their approach, collectively offering a more comprehensive view of the landscape.
  • Licensing
    Perspectives from across the archival footage licensing landscape on how generative AI is reshaping licensing, including emerging attribution and consent frameworks and shifting client expectations.
  • Copyright
    Generative AI and copyright, and what it means in practice for archives and those licensing their material.
  • Open Forums
    There will be two open forum sessions during the day, allowing participants to ask questions and share information.

Speakers include:

  • Ottar Anderson, DOAWG
  • Rachel Antell, Archival Producers Alliance
  • Patricia Aufderheide, American University
  • Jefferson Bailey, Internet Archive
  • Lou Burkart, Eye Filmmuseum
  • Williams Cole, Documentary Filmmaker
  • Luciana Duranti, InterPARES Trust AI
  • Charlie Eckert, Global Imageworks
  • Brenda Gunn, University of Virginia Library
  • Dave Hansen, Authors Alliance
  • Elizabeth Hansen, Texas Archive of the Moving Image
  • Shanna Hollich, CC Signals
  • Krista Hollis, The Menil Collection
  • Jesse Johnston, University of Michigan School of Information
  • Heather Lowrie, Former CISO & Advisor
  • Bertram Lyons, Magnet Forensics
  • Kate Murray, Library of Congress
  • Dale Nelson, Donaldson Callif Perez
  • Yvonne Ng, WITNESS
  • Kay Page, FOCAL
  • Brendan Quinn, IPTC
  • Brian Real, University of Kentucky School of Information Science
  • Megan Scott, Woodson Research Center
  • Eric Scouten, CAWG
  • Nick Spark, Periscope
  • Garth Stewart, Digital Preservation Coalition
  • Keir Winesmith, National Film & Sound Archive


Steering Committee

Trust in Archives Initiative Team


Co-Directors

  • Laura Rooney, Managing Director, Association for Moving Image Archivists
  • Rachel Antell, Co-Director, Archival Producers Alliance

Steering Committee

  • Fabio Bedoya, Head of Film Restoration, Filmfinity, Ltd
  • Krista Hollis, Archivist, Menil Collection
  • Yvonne Ng, Senior Program Manager, Witness
  • Kay Page, Managing Director, FOCAL International
  • Michele Resendez, Technical Business Analyst/Solution Architect
  • Philip Sulentic, Cataloger/Researcher, MPI Stock Footage Archive
  • Kevina Tidwell, Special Collections & Outreach Librarian,  Center for Brooklyn History

Additional Resources

RESOURCES

Resources are currently in English and skew toward the United States in relevance. TAI is international in scope, and we want this list to be as well, we especially welcome suggestions of resources from outside the U.S. This page is updated regularly and is not comprehensive. We encourage suggestions and feedback through our Suggestion Form.


TAI RESOURCES


GENERAL RESOURCES

Content Authenticity and Provenance in the Age of Artificial Intelligence: A Call-to-Action for the LAMs Community
  • Released in February 2026 as a product of the C2PA for G+LAM Community of Practice, the white paper  advocates for libraries, archives, and museums (LAMs) to take proactive and pragmatic steps to ensure that digital collections content, especially content impacted by AI at any point in its lifecycle, remains authentic, transparent, and verifiable from creation through access in order to meet the LAMs community’s mission of public trust.
University of Virginia Archival AI Protocol
  • A practical approach for evaluating AI requests involving cultural heritage collections. It provides AI training and access standards for archival organizations and is organized around a simple rule: “Irreversible models do not get access unless item-level provenance and meaningful attribution can be demonstrated in practice, and the archival organization retains contractually enforceable control to stop further use.”

Context Matters: Building Trust in Digital Content

  • Presentation on how content transparency can strengthen trust across the digital ecosystem and how secure, standards-based solutions are being applied across a wide range of real-world settings. Provenance technologies can help verify digital content, support evidentiary integrity, and inform policy solutions for a more secure and trustworthy information environment.

AI Literacy

Stanford Artificial Intelligence Index Report (2025) (2026)

  • Data in layman’s terms to guide the understanding of the AI industry

Empire of AI: Dreams and Nightmares in Sam Altman’s OpenAI By Karen Hao ISBN 978-0-59365-750-8 

  • New York Times Best Seller deep dive into the organizational foundations and goals of main AI companies and specifically OpenAI (ChatGPT, backbone to Microsoft’s AI initiatives)

World Privacy Forum (International)

Licensing/Rights Considerations

WIPO (2019). WIPO Technology Trends 2019: Artificial Intelligence. Geneva: World Intellectual Property Organization. (International)

  • World Intellectual Property Organization intends for this report to be a factual basis for policy discussions about innovation in AI. Based on a detailed study of patents and other information, it aims to shed light on the trends in AI since the field first developed in the 1950s. Research has involved the analysis of patent data related to AI inventions, as well as data on scientific publications, litigation filings and acquisition activity. These data findings are discussed in detail and accompanied by commentary and industry perspectives from more than 20 of the world’s leading experts in AI
  • Other WIPO resources (Intellectual Property and Frontier Technologies)(2024 Guidance Update on Patent Subject Matter Eligibility, Including on Artificial Intelligence (United States of America))

U.S. Copyright Office: AI report (United States of America)


LibGuides

UNM Libraries LibGuide

CCNY Libraries LibGuide

NC State University

George Mason University LibGuide

Syracuse University Libraries LibGuide

FIU Libraries LibGuide 

  • Section on librarianship

ECU Libraries LibGuide: A Guide to Artificial Intelligence (AI) for Students: Environmental Impacts

AI & Machine Learning Risks in Cybersecurity via University of Tennessee Knoxville

AI Use/Restrictions and Challenges in Archives

Patricia C. Franks, “Records and Information Management,” 3rd ed. (Chicago: ALA-Neal Schuman, 2025). 584 pp. ISBN 979-8-89255-588-3.

  • Seminal text updated to reference AI and machine learning (ML) in all fourteen chapters of the book as well as 2 new chapters on the subject

The University of Virginia Archival AI Protocol

Library and Archives 101: AI and the False Promise of Control

  • Written in response to the UVA Protocols

The Crisis Is Not Data. It Is Context.

  • Written in response to the UVA Protocols

Larson, Mary. 2026. “Oral History Encounters AI: An Exploration of Core Principles and Best Practices, Context and Consent.” The Oral History Review 53 (1): 93–110. doi:10.1080/00940798.2026.2625663.

American Archivist Generative AI Statement

  • Provides language that may be useful for creating parameters around AI use

Rockefeller Archive Center Documentation: AI Use in Our Archival Processes

  • Document outlines the reasons why RAC doesn’t don’t currently use AI in archival processes – including archival appraisal, acquisition, arrangement and description (processing), digital preservation, and access – as well as how RAC supports user communities who want to employ AI or other machine-assisted research methodologies in the course of their work. It does not address any potential use of AI in RAC business processes, and it is not intended to be an organizational AI use policy.

Padilla, Thomas. 2019. Responsible Operations: Data Science, Machine Learning, and AI in Libraries. Dublin, OH: OCLC Research.

  • Research agenda presents an interdependent set of technical, organizational, and social challenges to be addressed en route to library operationalization of data science, machine learning, and AI

Amanda Barajas, “AI in Archives: Reexamining Roles Between Archivist and Machine,” WOVEN: An Interdisciplinary Journal of Dietrich College 7, Fall (2025): 57-72.

  • Systematic literature review examining the current literature surrounding AI applications in archival spaces; interviews with archivists

Sonia Yaco, Bala Desinghu, Claire Warwick, and Richard Anderson, “What Can AI Do for Special Collections?,” American Archivist 88, no. 2 (2025): 441-473,

  • In-depth analysis of their experiences with specific AI tools applied to untranscribed documents (handwritten and type-written) and photographs. The evaluated tools range from end-user generative AI to APIs requiring Python programming and include software that is commercial and open-source; fee-based and free; web browser-based and standalone; and run in desktop, mobile device, and high performance computing clusters environments. Application scenarios extract text from images, perform complex pattern matching, and generate metadata.

International Research on Permanent Authentic Records in Electronic Systems (InterPARES) Trust AI Research Studies

  • Multinational interdisciplinary project to identify AI technologies useful to archives, determine their benefits and risks, and ensure that archival concepts and principles inform the development of responsible AI, including through research

Taxonomies

IPTC Standards

IPTC Photo Metadata Working Group

Program for Cooperative Cataloging (PCC) Standing Committee on Standards

AI4LAM Speech-to-Text Working Group and Transcript Provenance Metadata Elements

Coalition for Content Provenance and Authenticity (C2PA) (Content Credentials

  • Develops open, global technical standards for Provenance and Authenticity

Preserving Intent in Nonfiction Media: A Responsible Approach to AI Enhancement | Topaz Labs

Example tutorial for an image upscaling workflow in AI drawing 


AI Toolkit for Archivists Webinar Series

AI Toolkit for Archivists Webinar Series

As GenAI technologies increasingly shape how media is created, modified, and reused, archives face a range of questions related to authenticity, provenance, intellectual property, and ethical use. Developed by practitioners from across the field in TAI’s interdisciplinary Working Groups, , and refined through a community review process, these tools provide practical guidance to support the stewardship of archival materials in this evolving context.

This free, four-part webinar series introduces the Trust in Archives Initiative’s AI Toolkit for Archives.

Each session highlights one of the tools and is led by members of the working groups who developed them. The webinars combine presentation with time for discussion and questions. Participants will have the opportunity to explore shared challenges, compare approaches, and consider how these tools may be adapted across different organizational contexts, while also looking ahead to how the tools may evolve and what additional resources may be needed.

__________________________________

Assessing Authenticity — Due Diligence in the Age of AI

June 16 | 9:00am – 10:00am (Pacific) | Presentation Recording here.

This session focuses on the Due Diligence Questions tool, designed to help archives evaluate the authenticity and provenance of materials before accession. The webinar will include a presentation of the tool, its development, and how it can be applied in practice. Discussion will explore the concerns that these questions seek to address, followed by an opportunity for participants to share experiences and compare practices across institutions.

Yvonne Ng is an audiovisual archivist and a Senior Program Manager at WITNESS, where she trains and supports people to archive and preserve their human rights documentation. She currently serves on the Board of the CAW Collective and on the steering committee of the Trust in Archives Initiative (TAI). In 2024, Yvonne received the Alan Stark Award from the AMIA in recognition of her contributions to moving image archives and the association. Yvonne holds an in Moving Image Archiving and Preservation from New York University. 

Philip Sulenic currently serves as a member of the Steering Committee for the Trust in Archives Initiative (TAI). He began working for WPA Film Library in 2016 as a Researcher and Cataloger, continuing to do so during the company’s transition to MPI Stock Footage Archive. In addition to cataloging and digitizing MPI’s collections, Phil works with colleagues to promote newly digitized clips through the MPI’s social media accounts. Philip received his Masters in Library and Information Sciences, with a concentration in archival management, from Dominican University.

__________________________________

Content Licensing — Navigating Rights in the Age of AI

June 23 | 9:00am – 10:00am (Pacific) | Presentation Recording here.

This session focuses on the Licensing Templates, designed to protect the integrity of archival materials used in production and publication contexts. The webinar will include a presentation of the tool, the templates, and how they can be applied in practice. Discussion will address evolving questions around rights, permissions, and responsible use, followed by an opportunity for participants to share experiences and compare approaches across organizations.  The presentation portion of the webinar will be recorded; however, the Q&A and discussion will not be recorded in order to allow space for open and candid conversation.

Charlie Eckert is an archival producer who uses investigative journalism skills to locate hard-to-find materials and elevate narrative storytelling. Charlie is a member of Global ImageWorks’ internationally recognized team of audiovisual research and clearance specialists, offering archival footage research, copyright clearance, and licensing services.

Krista M. Hollis is the Assistant Archivist at The Menil Collection and holds a B.A. in Art History from Texas State University (2018), an MLIS with a Certificate in Archival Studies from Louisiana State University (2023), and is a LEED Green Associate.  Krista is a member of the Trust in Archives Initiative Licensing Language Committee and Steering Committee, the Treasurer of the Society of Southwest Archivists, Chair of the Programming Committee for the Archivists of the Houston Area, and volunteers at Orange Show Center for Visionary Art as their Special Collections Manager. Research interests include sustainability, systems thinking, and reparative practices; these are the lenses through which Krista approaches the challenges presented by emerging technologies.

__________________________________

Strategic Engagement with Technology Companies

July 8 | 9:00am – 10:00am (Pacific) | Presentation Recording here.

This session explores an inside‑out approach to archival practice, focusing on how organizational self‑assessment can inform and strengthen engagement with AI technology companies. It will introduce the Engaging with AI Tech Companies toolkit, designed to support archives in navigating relationships with AI developers and platforms.

The webinar will present the overall guidance framework, walk through its key components, and demonstrate how the tool can be applied in practice. Discussion will address potential risks and opportunities, as well as strategies for responsible collaboration in a rapidly evolving landscape. Participants will also be invited to share their own experiences of engaging with technology companies and to compare approaches across different organizational and national contexts.

The presentation portion of the webinar will be recorded; however, the Q&A and discussion will not be recorded in order to allow space for more open and candid conversation.


Michele Resendez is a technology professional with extensive experience in the energy and telecom sectors, specializing in Solution Architecture, Technical Business Analysis, and QA. She works with internal technology teams as well as third-party vendors designing and developing end-to-end solutions that meet business goals with focus on efficiency, compliance, and customer facing needs. She enjoys finding ways to bridge strategic business goals with technology function that streamline and bring value, with a proven record of leading process improvements. Michele works to see past the new and shiny tech, digging into the grit of what is really necessary. Prior to working in technology, Michele also has previous experience working with private film collections as an archivist, with film memorabilia, moving images and audio restoration.

Kay Page is the Managing Director of FOCAL International, the not‑for‑profit trade association representing the global footage and content licensing industry, alongside technical specialists in post‑production, preservation, restoration and related technologies. With a career rooted in television – including roles at ITV and All3Media – and experience as an independent consultant, Kay has extensive expertise in archiving strategy, rights management and licensing. She is a passionate advocate for the creative and commercial value of archive content.

__________________________________

Speaking the Same Language — Taxonomies for AI-Generated and Altered Media

July 14 | 9:00am – 10:00am (Pacific) | Presentation Recording here

This session focuses on the Taxonomy tools, developed to support shared language and consistent description of AI-generated and AI-altered content. The webinar will include a presentation of the tools, their development, and how they can be applied in practice. Discussion will address challenges in implementation and the need for adaptable vocabularies, followed by an opportunity for participants to share experiences and compare approaches across different contexts.

Fabio Bedoya is a film restoration specialist based in London whose work focuses on machine learning workflows for film restoration and audiovisual heritage preservation. His recent research explores open-weight AI models for chroma recovery in faded film and accessible restoration workflows for archives. He has presented internationally at conferences including AMIA Conference, FIAT/IFTA, IASA, and JTS. His work spans commercial restoration, technical research, and collaborative projects with archival institutions across Europe, Southeast Asia, and the Americas.

Kevina Tidwell is the Special Collections and Outreach Librarian at CBH. In this role she provides reference services and teaches classes on archival research to groups ranging from primary school to college to older adults. She previously worked as an archival producer for documentary films and television, performing research and designing media databases. She holds an MLIS from the Pratt School of Information and a BA in American History from Arizona State University.


This series made possible through support from the National Film Preservation Board. 


Tools: User Stories


USER STORIES

Over the past year, conversations within the TAI Authenticity working group have revealed that the exponential growth of generative AI is affecting archives, archivists, and their moving image collections. Inspired by the Library of Congress’ user stories for C2PA implementation in Government and Libraries, Archives, and Museums, the TAI Authenticity working group asked AMIA members to submit user stories to help us better understand specific concerns regarding GenAI as they relate to different roles and types of archives within the community. The stories below come from Authenticity Working Group members and from participants at our 2025 AMIA conference. We continue to seek and welcome new submissions. These user stories offer insightful perspectives that help us create tools and resources that will further our mission of ensuring authenticity, transparency, and trust.


Yvonne – AV archivist at human rights organization

As a human rights archivist, I want to feel assured that the documentation I am collecting is genuine (i.e. it is what it says it is). In my context, I may be uncertain about authenticity because videos are often captured by anonymous or unknown frontline witnesses, and uploaded to social media and chat apps, where they are often re-shared by others. Manipulated and misleading media proliferates on these platforms, including by authoritarian actors with resources to create misinformation campaigns that exploit mistrust and confusion, which undermines my ability to discern what is true.

Besides wanting to describe content accurately in my archive, I need to show some evidence of authenticity / how I determined authenticity when I provide these materials to users. My users may include legal professionals, fact-finders, human rights advocates, journalists, and communities impacted by human rights violations. Some ways that these users may accept media as authentic might be if there is testimony or corroboration from a trustworthy source, if there is an assessment of authenticity from a trustworthy expert, if there are distinctive markers of authenticity in the object itself, or if the process or system that created the documentation is known to ensure authenticity.


Phil – Cataloger and Researcher at a stock footage archive

As a cataloguer and researcher for an archival film company, authenticating moving image collections is an important part of maintaining trust with patrons that seek to view and/or license our collections. It is my responsibility to review footage not yet publicly available for viewing, and provide the proper descriptive metadata elements. Crucially, this includes providing exact or estimated dates, places, and people of note. Trust is important for a small archival film company. If I know the work I’m doing within the company is based on authentic film or tape-based material, then that will provide confidence for any patron that may have questions about, or seeks to license, our material. C2PA, from a technical level, may not be of much use to the collections we already possess, but adhering to baseline standards of authentication would certainly be helpful


Greg – Librarian at a university

As a curator at a university film archive my mission is to support the work of students and faculty by enabling trusted access to the university’s film collections and providing subject matter expertise to guide their inquiry. Few students have experience with moving images beyond smart phones, social media, and YouTube. The GenAI revolution in synthetic imagery threatens to increase the gap between their lived experiences and the material past, a gap that undermines critical thinking and diminishes an appreciation of our democratic ideals.

Introducing students to the concept of media provenance and showcasing to them the unique opportunities they have at our university to interact with and learn from an extensive, global film record of the 20th century has become for me an imperative. Our film archive can support this work but we need new models—relying on streaming our collections from the web as the primary (perhaps only) mode of access will no longer suffice. The ubiquity of Gen AI content (and soon the facility with which convincing historic imagery can be conjured) urges us to create learning spaces in which quality access to archival media for citation, illustration, and reuse in research projects (even reuse in conjunction with Gen AI) regrounds students and faculty in a relationship between the digital objects they manipulate and the material films from which they are derived.


Jennifer – Restoration and Preservation Manager

Working with film and archival collections, I have many concerns about generative AI and making sure our content is authentic. I am interested in non-generative AI tools that can help us restore, preserve, and provide access to more moving image materials


Amber – AV Preservation Librarian

I have several concerns about generative AI within the scope of a preservation librarian. GenAI can bring into question how we authenticate collection materials as genuine. Language within donor agreements and licensing agreements does not yet factor in concerns around generative AI. How Gen AI tools may be used for generating metadata and captions/transcripts for accessibility is a concern. I have ethical questions about uses of materials in the AI context. I am concerned about the technological superiority of a small number of tech companies in connection with authentication tokens like C2PA.


Margaret – Film Archivist

As a film archivist working within Special Collections at a large university library, I am concerned with the possibility of inauthentic reuse of our footage without our knowledge or permission.


Danica – Archivist

As an archivist working with the stories of everyday people, I am concerned about the notion of “findability” seen as an uncritical positive. Who are materials more “findable” for? I am concerned about what discovery tools will exist in 10-20 years, and where that leaves the right to be forgotten. I am also concerned about what gen AI is doing to the environment.


Ilana – Archival Producer

I conduct research for documentary filmmakers, and I’m concerned about accidentally passing on inauthentic content to filmmakers I work for, especially content from stock footage houses.


Nicole – Processing Archivist

As a processing archivist working with personal materials, I am concerned about the privacy and ecological impacts of generative AI. In terms of privacy, donors could be concerned as their personal reputations would be at stake. Furthermore, as AI becomes more ubiquitous, I worry  that I may be using AI without knowing it.


This resource is part of a toolkit created by the Trust in Archives Initiative. © 2026. Licensed under the Creative Commons Attribution–NonCommercial–ShareAlike 4.0 (CC BY-NC-SA 4.0) license.


Version 1.0 – April 2026. 

Tools: Strategic Engagement


STRATEGIC ENGAGEMENT WITH TECH COMPANIES: AUDIO VISUAL ARCHIVES ENGAGING WITH AI TECH COMPANIES

AI Technology Companies (“AI Tech Co”) increasingly seek what archives hold—rich media collections to train their multimodal and large language models (“AI”). Many archives have already had their online collections scraped without permission and are now facing offers from companies eager to secure further access.

To support archives navigating these pressures, we are developing decision-making rubrics to help institutions assess collaboration opportunities with AI Tech Cos.

These tools are designed to guide archives in weighing whether such deals represent sustainable business opportunities that strengthen their futures—or risky bargains that could compromise their long-term best interests. This paper serves as part of that tool, and is intended to help as a comprehensive resource for guidance on some key considerations and critical questions to ask.

The document covers:
• What is Generative AI?
• What type of companies want to obtain your data?
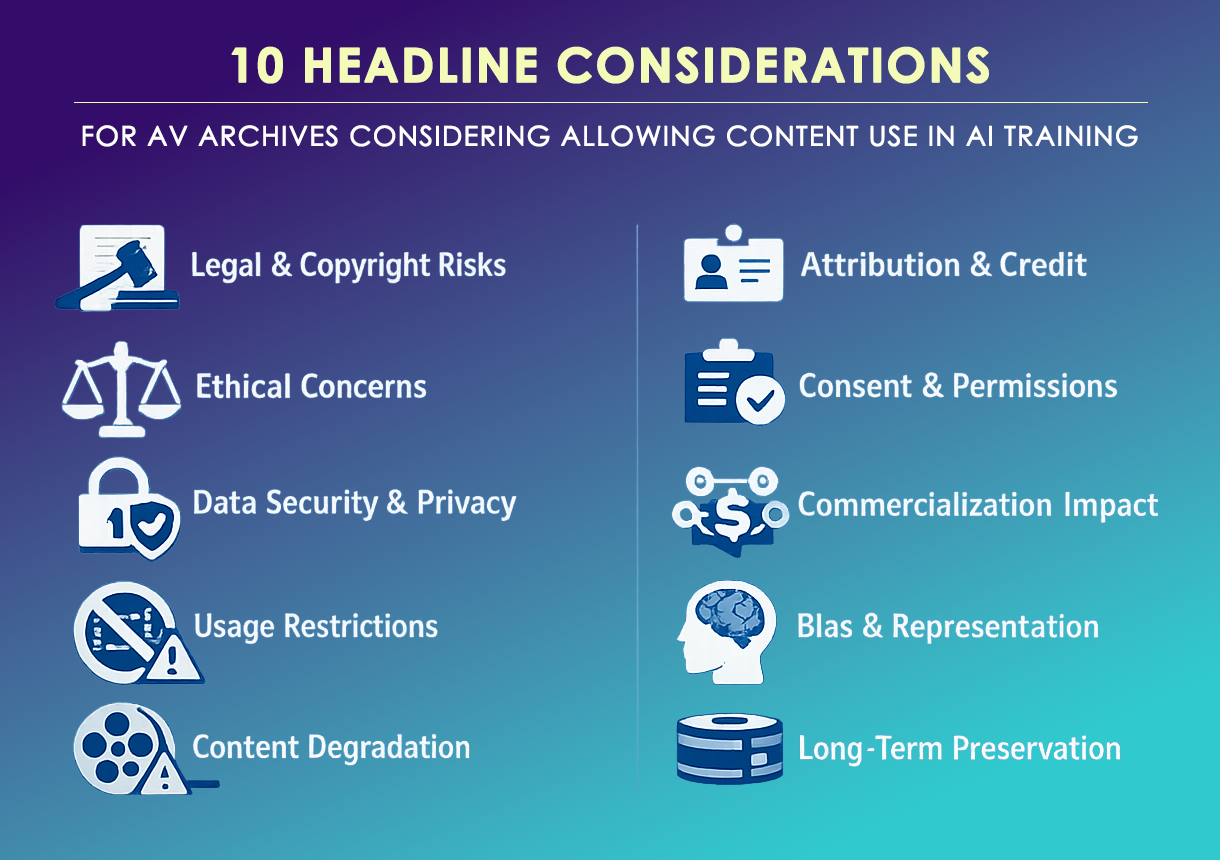
• 10 Key Things to Consider when looking at AI Tech Companies and why this is important
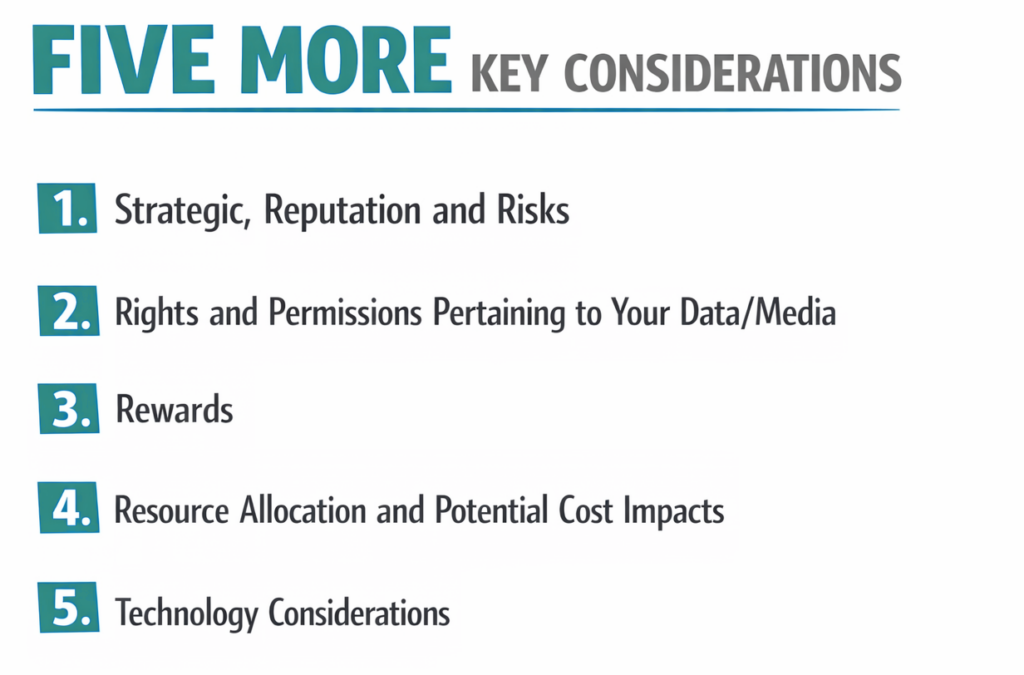
• Five more key areas to think about (introspective)
• Your Internal Technical Preparation
• Questions to ask the AI Tech Co.


What is Generative AI?

  • Generative AI (“GenAI”) refers to the use of AI to create new content, like text, images, music, audio and video.

  • GenAI models are trained on very large datasets from which they learn the patterns and structure and then generate new synthetic content that has similar characteristics.

  • More and more content globally is being created using GenAI tools, and audiovisual archives could be used to train data sets, should their rights and permissions allow it…

  • However, accuracy, authenticity and “truth” is a growing matter of concern

  • And GenAI content brings about new legislation and copyright/ownership questions

  • Audiovisual archives are challenged to implement policies to address these points; but the archive does not work in isolation from its wider organisation and must collaborate with stakeholders to design its policies

Who wants archive content?

Types of AI Tech Companies:

  • ‘Informed’ aggregators: Companies knowledgeable about the space with industry contacts who connect content libraries and negotiate deals.

  • ‘Digital Locker’ businesses: Organisations collecting content to become intermediaries between content owners and AI Tech Cos / LLMs, handling content delivery for a percentage fee.

  • ‘Jack of all trades’ aggregators: Companies seeking to acquire multiple rights types (FAST, VOD, AI) with limited transparency, typically offering 50/50 revenue sharing arrangements.

  • Bespoke language model builders: A fourth emerging model where businesses build custom language models based on specific content and license these models to various clients, creating subscription-based revenue streams.


10 Headline Considerations for AV Archives Considering Allowing Content Use in AI Training

  • Intellectual Property Rights: Ensure clear agreements on ownership and usage rights of AI-trained models

  • Content Licensing: Develop specific licensing terms for AI training purposes

  • Data Privacy: Implement measures to protect sensitive information in the content

  • Quality Control: Maintain oversight on how the content is used and represented in AI outputs

  • Ethical Use: Set guidelines to prevent misuse or creation of harmful content

  • Brand Protection: Ensure AI usage doesn’t negatively impact the archive’s reputation, or ‘brand’

  • Legal Compliance: Stay updated on evolving laws regarding AI and copyright, which may differ across jurisdictions/territories

  • Content Valuation: Assess the long-term value of your content in the context of AI training

  • Technology Partnership: Carry out thorough due diligence, how credible are they and are they in this for the long-term, do they have a good track record of working with others, do they have robust security and ethical standards

  • Revenue Sharing: Consider models for profit sharing from AI-generated content and work with AI Tech Co’s who will ensure you really benefit from a financial return.


Why Is This Important?

Before moving forward, consider philosophically why are you doing this? In what way does this promote the archives values?

Archives should carefully weigh these factors to protect their interests while potentially benefiting from the emerging AI landscape. The use of audiovisual and audio archives for AI algorithm training is a rapidly evolving field with significant promise for knowledge discovery, preservation, and access. However, it is equally fraught with legal, ethical, technical, and cultural complexities. Success depends on a commitment to robust governance, transparency, documentation, and human oversight, as well as ongoing dialogue among archivists, technologists, legal experts, and affected communities. Only through such a multidisciplinary and principled approach can the transformative potential of AI be harnessed while safeguarding the integrity, rights, and diversity embodied in audiovisual heritage.


Let’s take a dive into five key areas for further consideration before choosing to work with AI Tech Companies:

  1. Strategic, Reputation and Risks

  2. Rights and Permissions Pertaining to Your Data/Media

  3. Rewards

  4. Resource Allocation and Potential Cost Impacts

  5. Technology Considerations


1. Strategic, Reputation and Risks

  • Why are you doing this–what are the benefits of allowing access to your content?

  • Are there risks associated with allowing access to your content; does it devalue your content in any way ; are there consequences for your business model?

  • Have you vetted the AI Tech Co and compared them with others?

  • Consider what is valuable to your business versus what is valuable to the AI Tech Co?

  • To what extent can you define the deal terms on offer, or is the AI Tech Co fixed in their offer without space for negotiation?

  • Are you granting access to all or some of your archive? Can your content be segmented to meet an AI Tech Co’s specific needs and interests?

  • If there is a breach/technical problem with an AI company, directly or indirectly impacting your media, how might this impact your reputation and relationships with your underlying rights holders? If this problem puts the AI Tech Co out of business, how will you get your media back?

  • Some of the AI Solutions can generate harmful content of the persons in the media being shared with the AI Tech Co, for example Vishing Scams.  Because of the widespread abuse already to distort various types of media, audio, images and/or video considerations must be taken in this case. Have you considered this possibility?

  • With the level of risk for dealing with an AI Tech Co, careful consideration as to what AI Tech Co is chosen must be made. If you go with an unknown, small and new business there is no way to guarantee you will get your data back, or secured if that company is gone tomorrow. This can be another way of your data/media getting in the wrong hands. If the AI Tech Co goes out of business suddenly your contract/agreement with them is no longer viable. Consider only looking at larger reputable organizations?


2. Rights and Permissions Pertaining to Your Data/Media

  • How is your data/media being used by the AI Tech Co?

  • What is the right that you are granting to them – how is it defined – and can you grant that right?

  • Does your content have ethical, compliance or data privacy considerations?

  • Does your content have talent (actors, writers, presenters, contributors) attached and how is this handled in any deals?

  • Does your content have audio/music attached and how is this handled in any deals?

  • Who owns the resulting AI outputs if they are based on your content and data? If your data is being used to train the AI Engine, discuss with your internal groups that the trained media/or output might not be owned by your org.

  • At the end of the agreement, what happens to the content/data that you have supplied? What protocols are required for data retrieval or deletion should the partnership end?

  • What controls does the AI Tech Co have in place to ensure that they adhere to the grant of rights and that your content/data isn’t misused.

  • What is the established procedure for addressing compliance concerns with content after machine learning implementation? Are there any penalties associated with non-compliance?

  • Any engagement with an AI Tech Co that puts existing licensing, agreements or copyrights at risk from misuse can potentially put your organization at risk legally, however if your data is already publicly available on the open internet it will be very difficult to track who misused the data.


3. Rewards

  • What is the AI Tech Co’s compensation model – will you be paid by volume of content, type of content, etc.?

  • How long will you have to wait in your agreement to see a payment for sharing your content?

  • If your content is being used to train the AI, consider the potential for low profit margin or any profit at all since the output could potentially not be owned by your org.

  • Will you receive payment from the AI Tech Co purely for use of your data? Or will you have to wait until they make a profit? How transparent are they willing to be with this?

  • Does certain content (e.g. by genre) attract a premium?

  • If you have data to accompany your content, does this attract a premium? (data could be: descriptive, technical, rights, offline e.g. papers)

  • If you have “offline content” (rushes, production data, etc) that can only be accessed by going through you, does this attract a premium?

  • Are the upsides purely financial or can you get anything more from the technology relationships e.g. support (incl finance) to unlock the required content, data enrichment, catalogue enhancements?

  • If your content is being used to develop AI tools, would your organisation benefit from use of the improved tools and can your org have access to those tools – and include this in the deal terms?

  • Consider whether you can obtain enhanced data derived from content you provided to the deal for your own use. Establish clear terms for accessing, using, and redistributing these enhanced datasets, including specific exclusivity rights and usage limitations.

4. Resource Allocation and Potential Cost Impacts

  • At the earliest possible stage (before entering into a deal), you will need to assess if you have what an AI Tech Co is potentially looking for (volumes, subject matter, tech spec, etc.) – who will do this work?

  • Will you have any resources available to work alongside the AI Tech Co to ensure the correct data is being shared and operational processes are acceptable to the original agreement?

  • Have the resources that will work alongside the AI Tech Co provided an internal impact assessment on what they think the actual impacts would be for the work?

  • What effort is needed to make an actual deal work? Who are your internal (or external) stakeholders, are they all involved and do they have the time to input to the decision making process?

  • Will you incur any costs to enter into a deal e.g. legal, rights, technical or operational resources? This can include legal oversight, technical assistance in confirming your organization is prepared to interact with the AI Tech Co, and potential technical augmentation to prepare and secure your internal technical systems.

  • Who in your organization would own and approve a deal with an AI Tech Co?

  • Do you need to create or prepare assets and data in order to deliver to the AI Tech Co and, if there are costs to make your content ready, will the AI Tech Co contribute towards helping to unlock the content and make it ready? (see further Technology Considerations below)

  • If you are considering sharing your data, can you include considerations for watermarking your data for that particular sharing? This will keep your data traceable and ensure if data is leaked, you can trace it to a particular vendor.  Consider this extra cost as added insurance for your data. (however, if some of your data is already publicly available it will be difficult to trace that data back to the contracted AI Tech Co.)

  • Are you incurring one-time costs, or will you have costs and resource allocation ongoing throughout the life of the deal?


5.     Technology Considerations

The detailed technical questions included are intended to support a serious look inward at your organization’s technical capabilities, readiness and intentions so that you make careful decisions when planning to work with an AI Tech Co.  Before you move a conversation forward with outside AI vendors, seriously consider why this is something you want to pursue?  This is not something to rush into, there is no guaranteed financial return. There is a much higher risk of financial loss, reputation damage, and technical issues if the correct decisions are not made. As many institutions would like to entrust all the technical work (connectivity, moving the data assets, etc) to the AI Tech Co and leave all of the heavy lifting to them, there is even greater risk in allowing the decisions to happen outside of your organization, by that AI Tech Co. Do you really want to be the first in line for AI capabilities, even if the full business benefits are not yet defined? In a rush to get something new and potentially valuable (or perceived as valuable) for your organization, not vetting a company enough or asking yourselves the right questions could take your organization into a very negative situation.


Internal Technical Questions

Things to ask yourself prior to dealing with AI Tech Co (or any Technical Company)

The detailed technical questions included are intended to support a serious look inward at your organization’s technical capabilities, readiness and intentions so that you make careful decisions when planning to work with an AI Tech Co.

  • How up to date is your technology? Are you aware if the technology that houses your data/media is connected to any other sensitive organisational data like client information or employee data? Understand your technical capabilities. Your company Roadmap should include internal technical preparation prior to engaging your media with an AI Tech Co.

  • Do you manage your own technology around your data/media?  If not, and the technology that houses your media is managed by an outside party, have you shared your intent to interact with an AI Tech Co with that outside Media Management party?

  • What questions have they (the outside company that manages your data/media) provided to you about this?  Do they have restrictions? Have they suggested specific technology design specifications that the AI Tech Co would have to adhere to?

  • Will your outside technology partner that manages your media today have any restrictions or requirements that will incur costs for potential changes? Will they require a new Managed Services Agreement?

  • If you’ve identified the data/media you want to use with the AI Tech Co, is that data/media secure and separate from your other technology or at least isolated from data/media you do not intend to use?

  • Can you include your technical staff or someone that manages your data/media that can speak to the AI Tech Co to explain your systems and your technical requirements?

  • If you are not aware of your technology limitations and whether your media is properly segmented, you would need to identify persons (internal or external consultants) to do this.  What is the timeline for this review? Based on this review, what is the timeline and cost for preparation with a potential AI Tech Co?

  • Have you researched AI Tech Co’s to interact with? Have any AI Tech Co’s approached you? Have you reached out to any other organisations that may have worked with those AI Tech Co’s? What was their experience? [This also plays into the AI Tech Co’s credibility]

  • What function is the AI Tech Co providing to your organisation? Do you really require AI to make these changes for you? If it’s not about training for the AI application and maybe you are looking at services for Up-resing or resolution refinement or media restoration? Do you already have an existing application that might better suit your organisation until you can be assured that your technical software and hardware is secure and ready to connect with the AI Tech Co for services?

  • Have you priced similar tools that you might be able to purchase  and bring into your organisation (and get training on) instead of risking your data being shared with an outside AI Tech Co? (For example, OCI Media Flow by Oracle).

  • Have you talked to Technical Security specialists to discuss best practices to help you prepare your data and systems for dealing with an outside AI Tech Co?

  • Have you researched the potential risks with allowing the AI Tech Co to train their AI models on your data? For example: allowing an AI Tech Co to use your media for its training runs a risk of that AI application creating derivative works that look very similar to the media you provided which could lead to larger problems with licensing and even potential devaluation of the original media. (Also can lead to harming your media- See Risks section above)


Questions to ask the AI Tech Co

Something to think about when shopping around for AI Tech Co’s is that everything is a sale for them. You are dealing with sales people first. They will tell you ‘yes’ to anything to make you comfortable about choosing them and allowing them access to your data.  So although they might not be technically capable of doing some of the technical changes you inquire about, they will tell you whatever is needed to make you comfortable about doing business with them.  Ask them pointed questions, if you are not technical, have your technical staff or consultant on hand and ask them direct questions. Do your homework about that company.  Anything that you want to enforce about your concerns and use of your data you should be able to get in writing in an agreement with that AI Technical Company. Something else to think about: Some of the largest data breaches and exposures of internal proprietary data were done because of incorrect configurations with an AI Tool/Application (See McDonald’s/Paradox; ChatGPT Conversation History Leak; T-Mobile API Misconfiguration; etc).

One additional note: If you are considering discussion with an AI Tech Co or any Technical Company for work on your archives for support for things like up-resing or anything other than use for training the AI Tech Co’s AI Engine, many of these questions will help you plan your goals as well.


Capability

  • Can they assure their application is not using copyrighted material? (where applicable) Or is it at least annotated? How do they do this?

  • Have they done PoC’s (proof of concept) with other organisations?  Are they willing to share any of the inputs and outputs from those PoC’s? Share results.

  • Are they able to do a demonstration of their product for you without using your data/media? [This also plays into credibility]

  • If another company manages your data/media for you, share the restrictions with the AI Tech Co – and do they have any issues with these requirements?

  • How exactly will the AI Tech Co’s product work?  Will they connect to your internal systems?

  • How exactly do they propose grabbing your approved data/media and importing it into their AI application? In other words, how will they physically connect their systems to yours to obtain your data?

  • Can they provide a visual design showing a proposal of their systems connecting to your system and explain what will be used?

  • How will they process your data?  Can they share their design for this or is the actual AI processing a black box?

  • Will the AI Tech Co allow you to review and approve the system design they propose on how they plan to connect to your systems (in order to grab the data/media) before implementing it?

  • Can the AI Tech Co ensure that they provide a Secure Enclave for the data that cannot be co-mingled or shared with the AI Tech Co’s other client’s data?


Performance/Accuracy

  • How do they (the AI Tech Co) measure and evaluate their application’s performance?  How do they monitor this?

  • For Technical Services like Up-Resing:

    How do they handle hallucinations?  What does their mitigation plan look like for corrections? What sort of time frame could that be for corrections (potentially)?

    • For example: super refined resolution can add objects that weren’t there before or create unnatural/incorrect movements.  Phantom voices, incorrect words or changing speaker identities.

  • For Technical Services other than AI Training: How do they separate their specific services like image repair or Up-resing from the AI Training?

    • Does the AI Tech Co also provide data repair separate from the AI Training, and can they explain how they keep the data being repaired separate from training data?

  • Can the AI Tech Co provide performance metrics or error rates?

    • For example: For audio restoration or refinement – do they have a word error rate?

  • How do they, (AI Tech Co) handle scalability?

  • Does the AI Tech Co allow you to review and approve the final output of your data/media if you do use their AI services?


Privacy/Risk/Security – and More About Credibility
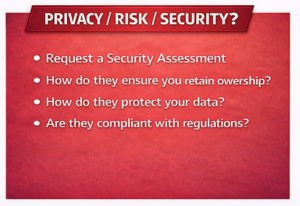
  • Request a Security Assessment/risk report from the AI Tech Co.

    • Why this matters: if the AI Tech Co  is directly connecting to your organisation’s infrastructure/systems to pull/push data/media for this AI process, knowing if they have had an assessment, or if there is a risk report on their systems can help with decisions on moving forward.  This would be good to understand if they are going to integrate with your systems to intake your data/media. Also to help in understanding the AI Tech Company’s risk factor of doing business with them. Risk = Likelihood x Impact.

  • Has the AI Tech Co indemnified themselves from hallucinations?

    • This question is handy if you are using the AI Tech Co for professional services like “Up-resing”.

  • Does the AI solution/design from the AI Tech Co rely on Third party vendors or other outside dependencies? If so, how are these dependencies secured? Is it possible for them to do a Software Composition Analysis check?

    • A Software Composition Analysis (SCA) check is an automated process done by a trusted outside party (cyber security firm) and checks the system components for vulnerabilities and creates a report outlining this called a SBOM, or Software Bill of Materials.

  • What best practices are followed by the AI Tech Co to monitor and secure the AI chain mitigating risks with other 3rd party vendor components?

  • Is there a fence between your organisation’s assets (data/media) and other client’s assets being stored and processed by the AI Tech Co within their systems?

  • How does the AI Tech Co restrict the use of your data/media exclusively to purposes you’ve authorised?

  • How does the AI Tech Co ensure that your organisation retains full ownership of all data/media put into their AI system(s)?

  • What assurances can they/AI Tech Co provide that your data/media will not be used for training, marketing or analytics without explicit consent?

    • This question is applicable in various forms regardless of how you engage with the AI Tech Co.  Maybe you will allow them to train their AI Engine but you don’t want your data to be used in demos/advertising.

  • Is the development team of the AI Tech Co off-shore? How will they ensure that all data/media, this includes inputs and outputs and training data (where applicable) remains within the geographical boundaries specified by your organisation?

    • For example: If the AI Tech Co is within your country’s location and adheres to your data/media privacy laws.  Their AI development teams might not be within the same geographical boundaries.  If your organisation is located within the United Kingdom and the AI Tech Co is as well, however their AI development teams are located in Belarus, or India, or another country not bound by your location privacy laws. How could you enforce the security of your data? Ask the AI Tech Co not to allow offshore development or storage with your original data/media.

  • Is their AI Engine/process within a secured closed loop and not touching the open internet?

    • This is not about user access (user access is outlined in the bullet directly above).  This is about the AI Tech Co’s actual AI Engine/Application and its overall design. If their design is exposed to the open internet, your data/media will not and cannot be secured regardless of their assurance, and is very much at risk.

  • If the AI Tech Co is directly integrating their systems to your organisation’s systems, ask them if they would be willing to do an AI specific pentest (“Penetration Test”) on the systems once integration is done?

    • A Pen Test or Penetration Test is an authorized test/attack done by a security personnel or security testing person to check system vulnerabilities in the network, application, or systems.  A simulated cyber attack that helps identify areas of concern so that they can be corrected to guard against bad actors.

    • Pentesting could be an added expense but necessary to ensure systems and their configurations are as secure as possible. Also find out who will be responsible for the Pentesting costs since it is not uncommon for companies to use outside consulting parties for this.

  • Has the AI Tech Co had a Pentest done on their AI model before?

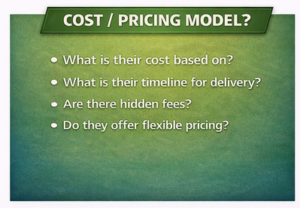
Potential Cost/Pricing Model

If you are shopping for AI Technical Services (restoration, Up-resing, etc) instead of being approached for AI Training, aside from the hidden costs listed above, below is a very high-level guide for potential cost models.

  • Based on your organisation’s requirements, what does their cost/pricing model look like? Do they have tiered pricing?

  • If you allow them to train their AI Engine with your data, do you get reduced pricing for this other service?

  • What is their cost based on? Is it per image/or track? By transaction? By minute or compute hour?

  • What is their timeline for delivery of your requested service? What sort of discounts do you get if the product isn’t on time or not to your specifications (and needs corrections)?

  • If you’ve checked the AI Tech Co’s references, if they used them for services other than AI training, did they feel comfortable with the costs of the service? Were there any surprise/hidden costs?


This resource is part of a toolkit created by the Trust in Archives Initiative. © 2026. Licensed under the Creative Commons Attribution–NonCommercial–ShareAlike 4.0 (CC BY-NC-SA 4.0) license.


Version 1.0 – April 2026. 

Content Licensing: Prohibited Use


CONTENT LICENSING LANGUAGE TEMPLATE:
PROHIBITING USE

The following content licensing language template is intended as an addendum for Archives that license archival material, especially for publication purposes. This license is the result of a collaborative effort by members of the Trust in Archives Initiative (TAI).

Consideration was given to the fact that many standard post-production techniques (including but not limited to color correction, image stabilization, dirt and scratch reduction, etc.) are now being performed by assistive Artificial Intelligence (AI) software. In many cases, Licensees may be unable to easily know whether software used is “AI powered” or not.

The focus of this template is to ensure the preservation, integrity, and authenticity of the archival content by preventing the use of AI software on it. For those Archives that may allow for limited use of AI on their materials, please see the Limited Use template here; TAI has provided both licenses as we recognize that Archives may license materials to projects with dramatically different publishing processes (such as a documentary or a museum catalogue).

Please note: The information contained in this site is provided for informational purposes only, and should not be construed as legal advice. Please have an attorney review before adding to your existing content licenses.

Addendum for Licenses Prohibiting AI Use

Licensor [name of institution] (referred to as “Licensor” below), maintains an archival collection (referred to as “Content” below), which Licensor makes available to licensees such as [name of client] (referred to as “Licensee” below) for use in its program (referred to as “Program” below). The Licensor wishes to make clear that, as a steward and conservator of archival material, maintaining the integrity and authenticity of the Content is the Licensor’s highest priority, and that the Licensee has a duty with respect to the handling of Content. As such, the use of generative tools (e.g., Artificial Intelligence “AI”, or “smart” software) including but not limited to generative software, Large Language Models (LLMs), Small Language Models (SLMs), or Vision Language Models (VLMs) – referred to categorically as “AI software” below – is prohibited on the Content being licensed by Licensee.

Furthermore, the Licensor does not permit the use of licensed Content, or any materials from its Content library, or associated metadata (including, without limitation, caption information, description, summary, or keywords) to be used for machine learning, data mining, or for training AI software, large or small language models, or other AI software tools. Furthermore, no permissions are granted to Licensee by Licensor, or to any third party or assignee, to train AI software on the Content as it appears in the Licensee’s Program.

If there is an intent to use AI software on licensed Content, the Licensee must receive prior approval from the Licensor. In the event that the Licensor believes that Licensee has breached this agreement, the Licensor shall provide written notice outlining the alleged breach and the reasonable steps that must be taken to remedy it (within x amount of time).


This resource is part of a toolkit created by the Trust in Archives Initiative. © 2026. Licensed under the Creative Commons Attribution–NonCommercial–ShareAlike 4.0 (CC BY-NC-SA 4.0) license.


Version 1.0 – April 2026. 

Content Licensing: Limited Use


CONTENT LICENSING LANGUAGE TEMPLATE:
LIMITED USE

The following content licensing language template is intended as an addendum for Archives that license archival material, especially for production purposes. This license is the result of a collaborative effort by members of the Trust in Archives Initiative (TAI).

The focus of this template is to ensure the preservation, integrity, and authenticity of the archival content. In cases where Artificial Intelligence (AI) manipulation is used, the template helps ensure that these changes are flagged, and a review is conducted to ensure compliance with standards established by the Archive.

Consideration was given to the fact that many standard post-production techniques (including but not limited to color correction, image stabilization, dirt and scratch reduction, etc.) are now being performed by assistive AI software. In many cases, Licensees may be unable to easily report whether the software used in post-production is “AI powered” or not.

For those Archives that may wish to outright prohibit any use of AI on their materials, please see the Prohibited Use template here; TAI has provided both licenses as we recognize that Archives may license materials to projects with dramatically different publishing processes (such as a documentary or a museum catalogue).

Please note: The information contained on this site is provided for informational purposes only, and should not be taken as legal advice. Please have an attorney review before adding to your existing content licenses.


Addendum for Licenses allowing for some AI Use

Licensor [name of institution] (referred to as “Licensor” below), maintains an archival collection (referred to as “Content” below), which Licensor makes available to licensees such as [name of client] (referred to as “Licensee” below) for use in its program (referred to as “Program” below). The Licensor wishes to make clear that, as a steward and conservator of archival material, maintaining the integrity and authenticity of the Content is the Licensor’s highest priority, and that the Licensee has a duty with respect to the handling of Content. This is especially important where the use of generative tools (e.g., Artificial Intelligence “AI”, or “smart” software) including but not limited to generative software, Large Language Models (LLMs), Small Language Models (SLMs), or Vision Language Models (VLMs) – referred to categorically as “AI software” below– is concerned.

The Licensor restricts the use of AI software on Content being licensed by Licensee. Any enhancement of Licensor’s visual Content beyond standard post-production (color correction, scratch and dust reduction, subtitling, etc.) by the Licensee must be disclosed and authorized; any enhancement of Licensor’s audio content beyond standard post-production (equalization, noise reduction, etc.) by the Licensee must be disclosed and authorized. Any AI software assisted enhancement that could affect the integrity of Licensor’s content (for example, adding detail or sharpening based on generative interpretation of visual artifacts; the addition of new, generative content to existing content; the addition of generative frames or handles to content; or the rendering of new speech or other audio based on existing material) is not permitted without written authorization by Licensor. Any enhancement to content in post-production by the Licensee that meets the above parameters must be disclosed, reviewed, and approved in writing by Licensor prior to publishing.

Furthermore, the Licensor does not permit the use of licensed Content, or any materials from its Content library, or associated metadata (including, without limitation, caption information, description, summary, or keywords) to be used for machine learning, data mining, or for training AI software, large or small language models, or other AI software tools.  Furthermore, no permissions are granted to Licensee by Licensor, or to any third party or assignee, to train AI software on the Content as it appears in the Licensee’s Program.

If AI software is used to alter or enhance Content through mutual agreement by Licensor and Licensee, the Licensee will disclose the use in the credits of the Program consistent with industry standards. (For examples, please refer to the Archival Producers’ Alliance crediting guidance).


SCHEDULE A

Licensor will review Licensee’s use of AI Tools on Content within [XX] Business days of request, Assets needed for approval process include:

  • Before and after representations (such as screenshots, .movs, .mp3s) for ease of comparison

  • Name of software used

  • Date of AI manipulation, if known

  • Prompts used, if applicable


This resource is part of a toolkit created by the Trust in Archives Initiative. © 2026. Licensed under the Creative Commons Attribution–NonCommercial–ShareAlike 4.0 (CC BY-NC-SA 4.0) license.


Version 1.0 – April 2026. 

Tools: Taxonomies


TAXONOMIES

Taxonomies Comparison Grid

The goal of the Trust in Archives Initiative (TAI) Taxonomies subgroup was to survey existing taxonomies and taxonomic guidance in order to describe AI generated or edited media (AI media). After surveying, the subgroup made a list of recommended taxonomic fields for cataloguing AI media. The IPTC Photo Metadata Working Group’s recommendations, first released for public comment on Aug 1, 2025, were a major jumping-off point. The goal was not to create a technical manual or a format-specific guide but a general guide that reflects emerging standards for describing AI media.

Surveyed taxonomies and taxonomic guidance

Members of the subcommittee sought examples of metadata for AI media by reaching out to their professional networks, including open requests for input from the AMIA email list, and multiple metadata communities on Slack. The standards that came to light span multiple formats and vary in technical specificity.

IPTC Photo Metadata Working Group
Program for Cooperative Cataloging (PCC) Standing Committee on Standards
AI4LAM Speech-to-Text Working Group and Transcript Provenance Metadata Elements
Coalition for Content Provenance and Authenticity (C2PA)
Various open linked data ontologies


Synthesis of surveyed taxonomies

Members of the subcommittee considered the following questions when synthesizing the surveyed taxonomies:

  • What metadata is unique to AI media? What information should be captured for this media that is not necessary for other media?

    • This encompasses technical, provenance, and ethical concerns.

  • What information is necessary to determine the veracity of AI media?

    • Authentication remains an evolving issue. IPTC and C2PA overlap in important ways, but they are not interchangeable, and adoption varies across vendors, platforms, and workflows. As a result, no single current standard guarantees complete provenance in every case. Cataloguers should therefore treat provenance metadata as partial evidence that must be interpreted in context.

  • Who is doing this cataloguing and when is it happening?

    • The members of TAI come from diverse fields, including non-profit libraries and archives, media production, and stock footage libraries. The person cataloging the media might be its creator or a downstream repository. The media might have known or unknown provenance. A cataloguer receiving the media may not be able to complete some of the fields recommended by TAI or may need to request specific metadata from the source of the media.

  • Where does the metadata come from?

    • In some cases, the metadata recommended in this guide will not be available even when provenance is known. Much of the metadata described here must be generated at the point of creation and cannot be entirely reproduced retrospectively. Documentation practices vary widely: some model developers publish model cards, system cards, dataset documentation, or provenance manifests, while others provide only partial disclosures or none at all. Cataloguers should therefore expect uneven metadata availability and record both what is known and what could not be verified.

    • Institutions that need to catalog AI media will need to become advocates for metadata access and transparency. In some cases, there will be no leverage to request transparency from AI companies; in others, the brokering of archival media from institutions to AI companies that need large data sets may be a point of leverage. In this developing field, libraries, archives, media producers, and others can advocate for access to the metadata they need to document AI media.

    • The format of the metadata will vary depending on whether it was recorded at the point of creation or retroactively described. It can be useful in either case, but may lack uniformity.

    • Even when provenance is partly known, AI-related metadata may be incomplete, inconsistently recorded, or unavailable to downstream repositories. Some workflows preserve detailed technical records, while others leave only partial traces. Cataloguers may therefore need to distinguish between metadata captured at the point of creation and metadata reconstructed later from surrounding documentation.

Sources of AI Metadata

  • A model card is a document that accompanies an AI model and describes what the model is, how it was trained or evaluated, its intended uses, known limitations, and relevant ethical or bias considerations. When available, model cards can provide a useful starting point for archival description because they may identify the model, summarize training or evaluation context, and document important constraints on interpretation and reuse. For a widely used introduction, see Mitchell et al., *Model Cards for Model Reporting*: https://arxiv.org/abs/1810.03993

    Model cards are not consistently available, however, and their level of detail varies widely. Some open models are accompanied by substantial documentation, while many commercial systems provide only partial disclosures or no model card at all. For this reason, cataloguers should treat model cards as one possible source of evidence rather than as a complete or uniform record.

  • Some relevant metadata may be embedded in the media itself or preserved in sidecar data, such as IPTC/XMP fields, C2PA manifests, timestamps, or exported workflow files. Other important information, including prompt text, prompt authorship, training-data disclosures, or internal processing notes, often must be requested directly from the creator, production team, or platform.

  • When exact technical metadata is unavailable, cataloguers may need to combine creator-supplied free-text descriptions with controlled vocabulary and local notes. In practice, requests should focus on the records most useful for establishing provenance: model name and version, prompt text, prompt writer, reference media, workflow or processing steps, date generated, and any available model card or provenance manifest. These details may be requested through deposit forms, acquisition agreements, creator questionnaires, or direct follow-up with the depositor or vendor.

TAI AI Taxonomy

AI Model

Definition: The foundational model name and version used to generate this media.
Example: “Wan2.2-T2V-A14B-Diffusers Text-to-Video”; “CogVideoX-2B”
Source: Model cards, system documentation, creator-supplied workflow files, platform job history, API logs, provenance manifests, or direct confirmation from the creator or vendor.

– Hugging Face `Model Cards` docs: https://huggingface.co/docs/hub/en/model-cards
– Mitchell et al., *Model Cards for Model Reporting*: https://arxiv.org/abs/1810.03993

Training Data

Definition: The collection of data used to train an AI/ML model, shaping its capabilities and biases.
Example: A dataset of newsreels containing war footage.
Source: Model cards, technical documentation, research papers, vendor disclosures, or creator-supplied notes. In many cases, training-data information will be partial, generalized, or unavailable and should be recorded with appropriate caution.

AI Text Prompt Description

Definition: The text instructions or other human-authored inputs provided to an AI system in order to generate, transform, or modify the media.
Example: “Enhance film grain, preserve original texture, upscale to 4K.”
Source: Source: Creator-provided prompt logs, workflow or project files, API request history, platform job exports, or written documentation supplied by the depositor. If the prompt is not embedded in the asset or a provenance manifest, it usually must be requested directly.

AI Prompt Writer Name

Definition: Name of the person who wrote the prompt used for generating this media.
Example: “Kevina Tidwell”; “Unknown prompt writer”
Note: May not always be known or necessary to capture.
Source:

Reference Media

Definition: Media supplied to an AI system as an input, source, or base from which new or modified media was generated.
Example: “Getty Images 2218833057”
Source: The source media itself, asset management records, project files, edit decision lists, workflow inputs, or creator-supplied documentation identifying the base or input media.

AI Workflow

Definition: The documented sequence of AI-driven steps, parameters, and tools applied to archival material. It describes how content was processed, from input to output.
Example: An Upscaling Workflow using ComfyUI, that can be easily replicated using the final output with the workflows embedded into a JSON file.
•  See https://dripart.mintlify.app/tutorials/basic/upscale.
•  Preserving Intent in Nonfiction Media: A Responsible Approach to AI Enhancement | Topaz Labs

Source: Exported workflow files (for example, ComfyUI JSON), project files, scripts, API logs, processing notes, standard operating procedures, or creator/vendor documentation describing the steps and settings used.

Date Generated

Definition: The date on which the media was generated, materially modified, or output by an AI-assisted workflow.
Example: 2025-01-12
Source: Embedded file metadata, provenance manifests, platform job history, project files, or creator-supplied production records. If only an approximate date is known, that uncertainty should be recorded in a note.

Next steps

Further work should be done to guide cataloguers on what metadata should be recorded, where to get it, and how to ask for it from AI media creators and AI companies, whether for individual media objects or for collections acquired in bulk.


This resource is part of a toolkit created by the Trust in Archives Initiative. © 2026. Licensed under the Creative Commons Attribution–NonCommercial–ShareAlike 4.0 (CC BY-NC-SA 4.0) license.


Version 1.0 – April 2026.